Post
Beyond the AI Hype: TheBestSI Wants to Change How We Understand Intelligence
TheBestSI joins AI software discovery, frontier model comparisons, transparent evaluation methods and research on superintelligence in one platform. A look at what it sets out to do.
Disclosure. TheBestSI is a sister publication in the same network, run by the same team as this site. This is a profile of it, not an independent review. We have not tested any product it lists or verified its rankings.
The short answer
TheBestSI (thebestsi.co) is an editorial and research platform with three pillars: AI Tools & Rankings, AI Models & Research, and Superintelligence. It says it separates hands-on testing, documented research and editorial analysis, and that affiliate relationships do not decide its rankings. Those are its own statements, which this site has not independently verified.
Artificial intelligence is becoming more capable, more accessible and harder to evaluate. TheBestSI is building a research platform that brings together AI software discovery, frontier model comparisons, transparent evaluation methods and the scientific and philosophical questions around superintelligence. Its central proposition is that understanding AI takes more than knowing which product is popular: it means examining what systems can do, how their capabilities are measured, and what their development could mean.
AI is no longer a single technology category. It is an ecosystem of models, applications, coding agents, research assistants, generative media systems and increasingly autonomous software. At the same time, questions about artificial general intelligence (AGI) and artificial superintelligence (ASI) are moving from specialist discussion into mainstream debate about science, economics, security and human progress.
TheBestSI brings these subjects together in one editorial platform: helping people choose AI tools, understand the models behind them, and investigate the longer-term evolution of machine intelligence. Available at TheBestSI.co, The Intelligence Authority, it is built around three connected disciplines: AI tools and rankings, AI models and research, and superintelligence.
The distinction is important. Choosing a useful AI application is a practical decision. Understanding why one model performs differently from another is a technical and scientific problem. Judging whether future systems could exceed human capabilities across a broad range of domains raises an entirely different set of questions. TheBestSI treats these as related but distinct subjects, so readers can move from immediate technology decisions toward a deeper understanding of the systems reshaping the world.
What three questions does TheBestSI ask about intelligence?
TheBestSI's defining idea is that AI cannot be understood through a single ranking or benchmark. It separates the subject into three areas, each answering a different question.
| Editorial pillar | The central question | What readers can explore |
|---|---|---|
| AI Tools & Rankings | Which AI products are suitable for a particular task? | Software directories, category rankings, product reviews, and practical comparisons |
| AI Models & Research | How do the underlying models differ in their capabilities and limitations? | Frontier model comparisons, coding models, reasoning models, open-source models, and benchmark analysis |
| Superintelligence | What would it mean for machine intelligence to exceed human capabilities, and what challenges could follow? | AGI and ASI definitions, intelligence explosions, alignment research, safety, and future scenarios |
These pillars create a broader editorial journey than a conventional AI directory. A developer can begin with coding assistants, compare the models behind them, then explore research on increasingly capable systems. A business leader can look at practical tools before examining model limitations, evaluation methods and governance. A reader interested in the future of intelligence can come from the opposite direction, starting with AGI and superintelligence before turning to the technologies available today.
The connecting principle is that discovering an AI product, understanding its underlying intelligence, and evaluating the implications of future AI are different tasks that benefit from different evidence. That gives TheBestSI a distinct identity: it is not only a software recommendation site, a model leaderboard, or a publication about hypothetical superintelligence. It aims to connect all three.
Why is finding the right AI tool harder than finding the most popular one?
The AI software market has a paradox at its center: more tools create more possibilities, and make choosing harder. Two products may both advertise AI-powered productivity while serving entirely different needs. A coding assistant built to understand a whole repository is not interchangeable with a general-purpose chatbot. A research engine built around academic literature solves a different problem from an answer engine that searches the live web. A powerful model may also be needlessly expensive or operationally unsuitable for a workflow.
TheBestSI addresses this through its AI Tools & Rankings pillar, which organizes software around use cases and describes capabilities, strengths, limitations and pricing considerations. The platform recognizes that usefulness depends on the task. Its AI tools directory is the starting point.
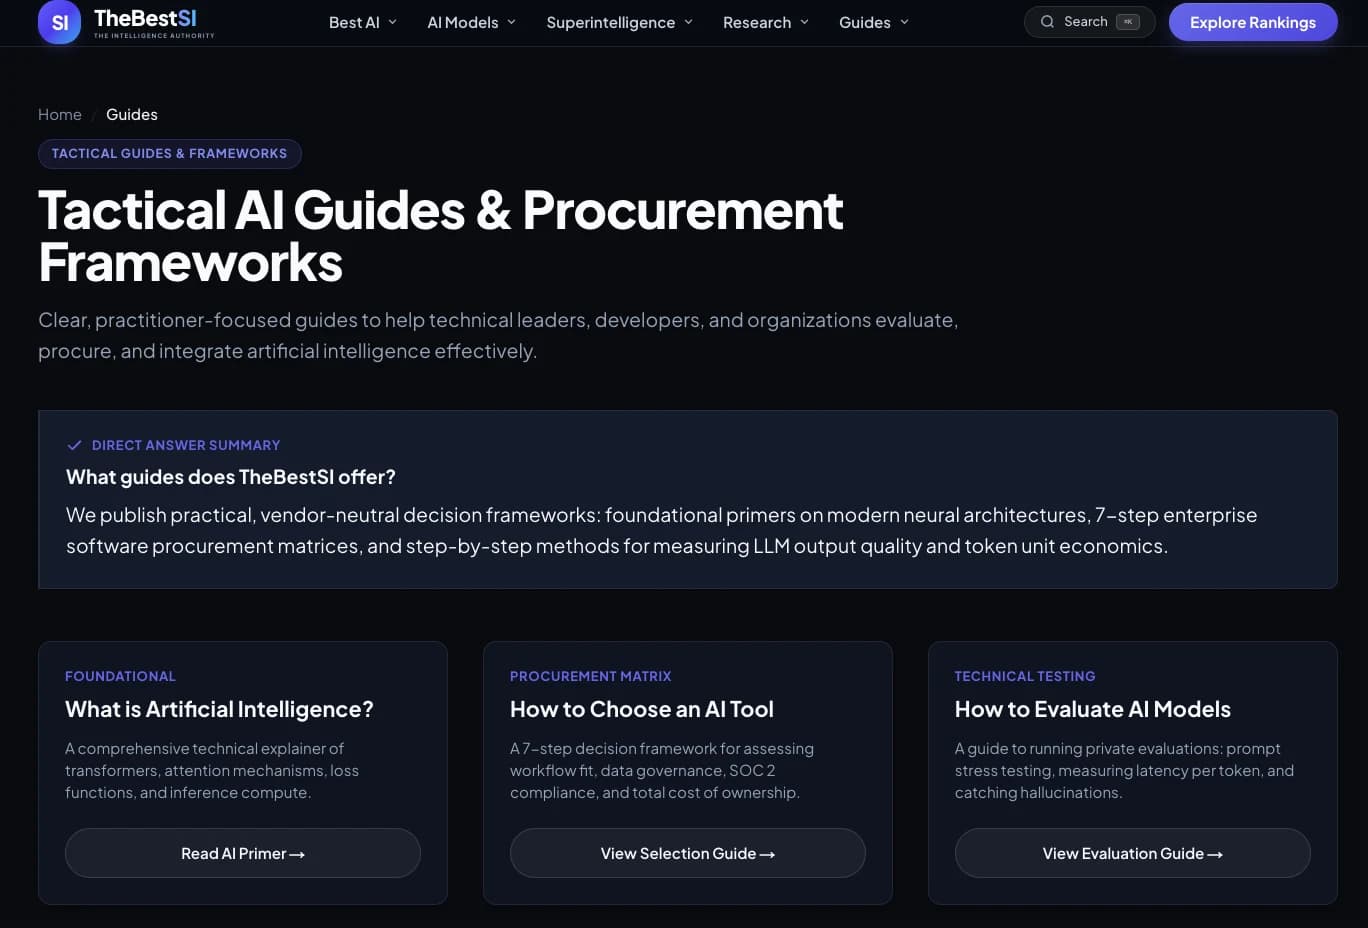
Inside the featured tool entries
The homepage presents several examples of products suited to different workloads. They illustrate the kind of distinctions a discovery platform needs to make.
Cursor: AI-assisted software engineering. Cursor is presented as an AI-first code editor designed to work with frontier models on complex development tasks. The platform highlights repository indexing, multi-file editing and integration with different models. These matter because real engineering involves more than isolated snippets: developers need tools that understand existing files, make coordinated changes and support iterating on implementation and tests. TheBestSI also names trade-offs, including usage limits and the cost of adopting a separate editor. See Cursor's official site and TheBestSI's coding tool coverage.
Claude: reasoning, coding and knowledge work. Claude is presented as an assistant suited to complex software engineering, technical writing and analysis. The platform highlights code generation, debugging, natural-language output and its Artifacts workspace, an example of an AI product extending from conversation into creating and previewing code and interactive components. How useful that is depends on the task, the implementation requirements and the quality of the output; a feature does not establish that a product outperforms every alternative. See Claude's official site and TheBestSI's ChatGPT vs. Claude comparison.
Consensus: research grounded in scientific literature. Consensus searches academic research and synthesizes findings from papers. TheBestSI highlights source-linked research, paper retrieval and the Consensus Meter. For a researcher, the difference between a plausible answer and a conclusion supported by published studies is crucial. A system that links summaries to original papers offers a route to checking the evidence, though users must still check that the cited research supports the answer. See Consensus and TheBestSI's research tool coverage.
Why do limitations belong alongside strengths?
A coding assistant may offer sophisticated repository workflows but impose usage limits. A research tool may provide source-linked answers but lack the flexibility of a general assistant. An answer engine may search current sources and still misattribute a claim or omit context. These are not footnotes; they decide whether a product fits a user. TheBestSI's featured entries distinguish intended workloads, key strengths and material trade-offs, which lets readers treat selection as a decision about requirements and compromises, not a contest one application must win in every category.
How do AI model comparisons differ from comparing applications?
An AI application is not the same thing as the model that powers it. The application determines much of the experience: interface, integrations, workflow and tools. The model contributes language understanding, reasoning, code generation and multimodal processing. The final experience depends on how they work together, so comparing models needs a different method from comparing applications.
TheBestSI's AI Models & Research pillar focuses on the underlying systems, with entry points for frontier models, coding models, reasoning models and open-source models. Its comparisons include ChatGPT vs. Claude and Claude vs. Gemini, looking at reasoning, code editing, long-context handling and workflow suitability.
A useful comparison starts by defining the capability being examined. A software-engineering model may need to interpret a large codebase, modify several files, preserve existing behavior and produce changes that pass tests. A research model may need to retain information from long documents and distinguish conflicting findings. A mathematical-reasoning model may need to solve unfamiliar problems and show its answers are correct. These are different workloads, and performance on one does not establish performance on the others.
| Evaluation dimension | What it examines | Why it matters |
|---|---|---|
| Coding and refactoring | How reliably a model handles code changes across multiple files | Helps developers assess suitability for real software engineering |
| Mathematical reasoning | How effectively a model solves demanding logical and mathematical tasks | Relevant to technical problem-solving and research |
| Long-context handling | Whether information remains usable when embedded deep in lengthy inputs | Important for document analysis, codebases, and research synthesis |
| Voice and multimodal interaction | How a system handles audio, images, files, and real-time interaction where supported | Helps assess suitability for interactive and multimodal applications |
| Test conditions | The prompts, configuration, model version, and environment used | Determines how results should be interpreted |
| Limitations and trade-offs | Where performance or practical suitability remains constrained | Prevents a narrow result from becoming an overly broad conclusion |
A model may do well on a benchmark and still be a poor fit for a deployment because of cost, latency, context limits or integration needs. A strong general-purpose model may not be the most economical choice for a repetitive, narrowly defined task.
Why do test conditions matter?
A comparison is only as informative as the conditions under which it was run. A credible evaluation identifies the models and versions tested, describes the task, discloses important configuration choices, explains the scoring and acknowledges limitations. For practical coding tests, that may mean recording whether tools could run commands, inspect files or retry failed operations. For long-context tests, it may mean defining input length and checking retrieval from different parts of the document. Without those details, readers cannot tell whether a result applies to their workflow.
The essential question is not simply which model scores highest. It is which model performs adequately on the task that matters, under conditions that resemble the intended use. Our own guidance is in how to read an evaluation; TheBestSI has its own guide to evaluating AI models.
Why can AI benchmark results be misleading?
Benchmarks play an important role in AI research, but they are not comprehensive measurements of intelligence. A benchmark measures performance on a defined set of tasks under particular conditions. TheBestSI addresses the issue in its AI Benchmarks Audit, which examines the limitations and assumptions behind benchmark claims. A high score can be informative without being conclusive.
- Narrow task coverage: a benchmark may focus on one skill and overlook others needed in practical work.
- Contamination and data overlap: if a model met benchmark material in training, its score may not reflect ability on genuinely unfamiliar problems.
- Evaluation design: small changes to prompts, scoring, allowed tools or procedure can change how a result should be read.
- Aggregation effects: a single overall score can hide large differences across task categories.
- Changing configurations: results from different versions or environments may not be directly comparable.
- Limited real-world validity: success on a controlled test does not establish reliability in a complex operating environment.
These limits do not make benchmarks useless. They define the questions to ask before drawing conclusions. A model that scores highly on a programming benchmark may still struggle with an organization's codebase, test infrastructure or conventions, and a good reasoning score does not show general intelligence across all cognitive domains. See also our checklist for reading benchmark claims and the explainer on benchmark contamination.
From scores to evidence
- Relevant benchmark results.
- Direct evaluation on representative tasks.
- Technical documentation and model specifications.
- Documented limitations and failure cases.
- Independent research where available.
- Evidence about cost, reliability and deployment requirements.
Combined, these give a more nuanced assessment than a leaderboard position, and a more useful one for real decisions. TheBestSI publishes evaluation records describing how it documents hands-on tests.
What does TheBestSI say about AGI and superintelligence?
The third pillar moves beyond choosing and evaluating current products to the future of machine intelligence. AGI and ASI are not two more product categories. They concern the nature and extent of machine capabilities, systems that generalize across many domains, and the implications of possibly exceeding human performance. These subjects involve technical research, competing definitions and unresolved questions, and need a different style of analysis from a product review.
What is artificial general intelligence?
AGI generally refers to AI systems capable of performing a broad range of cognitive tasks at a level that would count as general rather than narrowly specialized. There is no universally accepted operational definition, and researchers disagree about the capabilities, benchmarks and evidence that would establish its arrival. Doing well across many tasks does not by itself settle every question about general intelligence: evaluations must consider the breadth of tasks, the degree of autonomy, the reliability of performance and the ability to adapt to unfamiliar situations.
What is artificial superintelligence?
ASI is a hypothetical form of machine intelligence that substantially exceeds human cognitive performance across a very broad range of important domains. It describes a possible future level of capability, not a verified class of available software. Open questions include how such capabilities might emerge, whether systems could improve their own capabilities, how humans might keep meaningful oversight, and what safeguards would be needed. TheBestSI collects these in its superintelligence hub, including What Is Superintelligence? and AI vs. superintelligence.
| Concept | General meaning | Central question |
|---|---|---|
| Artificial intelligence (AI) | Computational systems designed to perform tasks associated with perception, prediction, language, or reasoning | What tasks can a system perform? |
| Artificial general intelligence (AGI) | A proposed form of AI with broad, general-purpose cognitive capabilities | How broadly can a system learn, reason, and perform across different domains? |
| Artificial superintelligence (ASI) | A hypothetical form of machine intelligence substantially exceeding human cognitive performance across virtually all important domains | What would follow if machine intelligence substantially surpassed human capabilities across a broad range of fields? |
The move from present-day AI to AGI, if it happens, cannot be assumed to follow one predetermined path, and ASI is not an inevitable result of reaching any particular benchmark. Responsible analysis has to separate established findings from hypotheses and forecasts. See TheBestSI's AGI vs. ASI guide and our own superintelligence and today's tools.
Could AI improve itself?
One of the most consequential ideas in the superintelligence debate is recursive self-improvement: a system that contributes to improving its own capabilities, potentially enabling further improvements. It raises questions about feedback loops, the speed of progress, the difficulty of forecasting, and whether human oversight could become harder as systems grow more capable. But AI-assisted research and software development does not establish that an uncontrolled intelligence explosion will occur. TheBestSI covers the concept on its intelligence explosion page.
- Capability: can a system contribute to meaningful improvements in the models, tools or processes that produce it?
- Reliability: do proposed improvements consistently work under independent evaluation?
- Generality: do improvements in one capability carry over to other relevant domains?
- Constraints: what technical, economic and physical limits affect the rate of progress?
- Control: can developers evaluate, constrain and monitor the system as its capabilities change?
These questions are related but distinct. Evidence that an AI system can help optimize code does not establish that it can autonomously and indefinitely improve every aspect of its own intelligence. Safety and governance decisions benefit from clear lines between demonstrated capabilities, plausible technical scenarios and speculative outcomes.
What does AI alignment and safety involve?
As systems become more capable, keeping their behavior consistent with human intentions and operating constraints matters more. Alignment research asks how to make systems act in line with intended goals, instructions and values, and covers specification, training, evaluation, interpretability, robustness and detecting undesirable behavior. It gets harder when systems operate in unfamiliar situations, use external tools or pursue objectives over long periods: a model that answers well in a controlled chat may behave differently once it has broad permissions in a software environment. TheBestSI's AI alignment and superintelligence risks pages connect these questions to the wider discussion.
- Goal specification: how can developers turn human intentions into objectives a system follows reliably?
- Robustness: does the system behave appropriately when instructions, data or conditions change?
- Interpretability: can researchers learn something useful about the internal mechanisms behind behavior?
- Evaluation: can tests find important failure modes before deployment?
- Oversight: can humans monitor, constrain and intervene in a system's actions?
- Security: can systems resist manipulation, misuse and attempts to bypass safeguards?
Progress in one area does not automatically solve the others. A model that follows instructions reliably may still be open to adversarial inputs, and a model whose internals are better understood may still need extensive testing before it is trusted in a high-stakes setting. No single evaluation can show a system is safe under every possible condition.
How does a research platform separate evidence from speculation?
A publication covering both current products and hypothetical superintelligence faces an editorial challenge: keeping consistent standards across subjects with very different levels of certainty. A current product can often be examined through testing, documentation and reproducible tasks. A claim about future superintelligence may rest on theoretical arguments, uncertain assumptions and competing readings of incomplete evidence. Treating the two as equally measurable would weaken both.
TheBestSI states that its approach distinguishes hands-on testing, documented research and editorial analysis, and that its coverage emphasizes primary documentation, technical papers and official disclosures.
| Evidence category | What it can establish | What it cannot establish on its own |
|---|---|---|
| Hands-on testing | How a particular product performed under documented conditions | That the same result will occur in every environment or future version |
| Documented research | What relevant technical papers, documentation, and disclosures report | That every reported conclusion is independently verified or universally accepted |
| Editorial analysis | How available evidence can be interpreted and applied to a question | That an interpretation is equivalent to a direct measurement or established scientific fact |
An evaluation might establish that a model completed a specific coding task under defined conditions. A broader analysis could consider what that suggests for software workflows. A discussion of future general intelligence needs additional evidence and careful treatment of uncertainty. The three kinds of work can inform one another but should not be conflated. This site uses a similar six-way evidence label on every claim.
Why does a methodology page matter?
A methodology page explains the criteria used, the evidence accepted and the limits of the conclusions. TheBestSI's methodology describes five core dimensions for evaluating AI software:
- Domain task fidelity.
- Context and state integrity.
- Data governance and privacy.
- Workflow ergonomics.
- Cost predictability.
Together they ask: can a tool do the intended job, can it use the information the task needs, does its handling of data meet the user's requirements, does it fit the workflow, and can its costs be anticipated? Their usefulness depends on how they are defined, measured and applied in individual evaluations.
How does it address editorial independence?
AI software discovery has an unavoidable commercial side. Products compete for customers, providers promote their capabilities, and publishers may earn revenue when readers buy subscriptions or use affiliate links. Those relationships do not automatically invalidate product research, but they make transparency about editorial decisions especially important.
TheBestSI states that affiliate partnerships and advertising do not determine its scores, rankings or editorial inclusion. Its trust resources include an editorial policy, an affiliate disclosure and a corrections register. An affiliate disclosure tells readers about commercial relationships, an editorial policy explains intended standards, and a corrections register records changes when published information needs fixing.
Consider a hypothetical comparison of two coding assistants, one paying an affiliate commission and one not. If the ordering were influenced by the commission, readers could not rely on it as an independent assessment. A commercial firewall separates revenue arrangements from editorial evaluation, and the principle should cover the whole process: product selection, testing, scoring, presentation and updates.
It is also important to separate a stated policy from evidence that it is followed. A disclosure is a starting point; the methodology, supporting records and actual editorial decisions determine how much confidence readers can place in the process. Credibility has to be earned through consistent execution over time. For this site's own arrangement, see our affiliate disclosure and editorial policy.
What do guides, research records and technical education add?
A ranking answers a narrow question: which products are strongest under a particular set of criteria? A research platform can help readers understand the criteria themselves. TheBestSI's wider structure includes practical guides, benchmark analysis, model comparisons and evaluation records, serving different stages of learning. A newcomer might start with What is AI?. A developer could move to How to choose an AI tool. A technical evaluator might look at benchmarks and methodology. A researcher interested in long-term machine intelligence could explore AGI, ASI and alignment.
A connected path for a developer adopting a coding assistant
- Find candidatesStart with the AI coding tools directory to identify relevant products.
- Understand the modelsUse the model comparison resources to see how underlying models differ and why test conditions matter.
- Define criteriaUse How to choose an AI tool to turn project requirements into selection criteria.
- Plan a testUse How to evaluate AI models to build a more systematic test plan.
- Check the methodRead the methodology and evaluation records to see how the platform's own conclusions are produced.
The same structure can support a researcher examining academic AI applications, a manager comparing business tools, or a reader trying to understand claims about superintelligence. The value lies in connecting discovery to understanding, rather than giving a recommendation without context.
What makes content useful for AI-powered search?
As people use search engines and AI assistants for increasingly complex questions, how technical information is organized matters more. Readers do not always want a list of products. They may want to know why two models differ, whether a benchmark supports a conclusion, or what researchers mean by artificial superintelligence. Answering well takes clear definitions, specific evidence, relevant context and an honest account of uncertainty.
- A clear definition: explain the central concept without making readers infer it.
- A direct answer: address the question before the background.
- Traceable evidence: link claims to primary documentation, research papers or test records.
- Defined scope: say which product, model, version or scenario is discussed.
- Explicit uncertainty: separate established findings from hypotheses and editorial interpretation.
- Useful context: explain why the finding matters and what it does not establish.
- Connected resources: link to related guides, comparisons, methodology and foundations.
A page on benchmarks should not merely list scores; it should say what the benchmark measures, under what conditions, with what limits, and how results relate to real-world tasks. A page on ASI should define the concept and distinguish it from current capabilities, not present speculative timelines as fact. This helps human readers and can make information easier for search and answer systems to read. But clear formatting and descriptive headings do not guarantee rankings or inclusion in AI-generated answers; those depend on quality, originality, accessibility and authority.
TheBestSI at a glance
| Question | Answer |
|---|---|
| What is TheBestSI? | An editorial and research platform covering AI software, model comparisons, evaluation methods, and superintelligence. |
| What is its primary purpose? | To help readers understand AI capabilities, choose appropriate tools, compare models, and investigate the future of machine intelligence. |
| Who is it for? | Developers, researchers, students, technology professionals, business leaders, and readers interested in AI research. |
| What are its three main pillars? | AI Tools & Rankings, AI Models & Research, and Superintelligence. |
| What products does it feature? | Examples on its homepage include Cursor, Claude, Consensus, and Perplexity Pro. |
| What model comparisons does it feature? | ChatGPT versus Claude and Claude versus Gemini, alongside coding, reasoning, and open-source model resources. |
| How does it approach evaluation? | It describes distinctions between hands-on testing, documented research, and editorial analysis, with an emphasis on transparent criteria. |
| What does its benchmark coverage examine? | The limitations and assumptions behind AI benchmark results. |
| How does it cover superintelligence? | Through research and explanations on AGI, ASI, intelligence explosions, alignment, and AI safety. |
| How does it address editorial independence? | It states that commercial relationships do not determine scores, rankings, or editorial inclusion, and provides policy resources. |
| Where can readers begin? | TheBestSI.co |
Can an editorial vision become lasting authority?
TheBestSI's ambition is broader than another collection of AI recommendations. It seeks to connect the practical decisions people make today with the research needed to understand the systems behind them and the questions that may shape the future of intelligence. That creates a demanding editorial challenge. Products evolve rapidly, models change, pricing is revised and evaluation results go stale, while research on general intelligence and superintelligence contains questions that product reviews cannot settle.
Three priorities for long-term value
- Reproducible evaluationsReaders need to know how products were tested, which versions were used, what criteria applied and where evidence is incomplete.
- Sustained research qualityModel comparisons, benchmark analyses and discussion of superintelligence should reflect the strength of the evidence, not the popularity of a narrative.
- Transparent editorial accountabilityMethodology, disclosures, corrections and clear attribution must stay integral to the process as the platform grows.
TheBestSI has set up a structure intended to meet this challenge. Its authority will depend on the quality and consistency of the work published within it.
Why is understanding intelligence becoming a practical necessity?
For much of computing history, the tools people used and the scientific questions behind them lived in separate worlds. AI is bringing them together. A business choosing a coding assistant may need to understand the limits of the underlying model. A researcher using AI to synthesize literature must weigh generated answers against source evidence. An organization adopting autonomous systems must look at governance, security and oversight as well as productivity. Meanwhile AGI and ASI raise broader questions about how intelligence should be defined, measured and controlled.
These questions are connected, but should not be confused. A useful AI product is not necessarily evidence of general intelligence. A strong benchmark result does not establish that a system is safe for every deployment. A theoretical scenario about superintelligence is not a verified forecast. The value of an independent research platform is in helping readers keep these distinctions while seeing how the pieces fit.
Its central question is not which AI product deserves the highest position on a leaderboard. It is more fundamental: how do we understand intelligence when the systems we are building are becoming more capable, the measurements we use remain imperfect, and the consequences of getting our judgments wrong may reach far beyond the software market? TheBestSI's answer begins with evidence, continues through research, and extends toward the unresolved questions that will define the next era of AI.
Start at TheBestSI.co for AI tools, model research and superintelligence.
Evidence in this article Editorial interpretation Our reading of what the evidence means. Judgment, clearly separated from the evidence itself.
Frequently asked questions
What is TheBestSI?
An editorial and research platform covering AI software, model comparisons, evaluation methods and superintelligence, at thebestsi.co. It is a sister publication of this site.
What are its three pillars?
AI Tools & Rankings, AI Models & Research, and Superintelligence.
How does it say it approaches evaluation?
It distinguishes hands-on testing, documented research and editorial analysis, and states that affiliate partnerships and advertising do not determine its scores, rankings or editorial inclusion.
Has this site verified TheBestSI's rankings or tests?
No. The statements about its rankings, testing and policies are the platform's own. We link to its methodology, evaluation records and corrections pages so readers can check them.
What is the difference between AGI and ASI?
AGI generally means AI with broad, general-purpose cognitive ability. ASI is a hypothetical level of machine intelligence that substantially exceeds human performance across virtually all important domains. Neither term has a universally agreed operational definition.
Sources
This article is editorial analysis. It cites no external sources and contains no product performance claims, benchmark figures, or policy facts.