Post
The AI Industry Has a Trust Problem. BestSuperintelligent.com Wants to Help Solve It.
An independent AI research platform that separates vendor claims from evidence, gives buyers practical tools to choose models and estimate cost, and makes its own limits visible.
Disclosure. This is a cover story about this site, written by its own editorial team. It describes the site's stated policies and tools; it is not an independent review of them.
The short answer
BestSuperintelligent.com is an independent AI research and comparison site that treats a vendor claim as different from a verified result. It labels every claim by source and date, offers a model finder and cost calculator, and publishes no ranking until at least two products in a category have fully evidenced evaluations. Today none has.
As artificial intelligence changes how people write software, conduct research, create content and run businesses, choosing the right tools has become a problem of its own. BestSuperintelligent.com takes a different approach to the crowded AI market: instead of treating vendor promises as proven performance, it separates claims from evidence, gives users practical tools to make informed decisions, and makes its own limitations visible.
The AI market has a discovery problem. Developers face an expanding selection of coding assistants and autonomous agents. Businesses must weigh competing models, subscription plans, security requirements and operating costs. Enterprise and government buyers face a harder question still: how can they justify adopting an AI system when the evidence behind its advertised capabilities may be incomplete?
BestSuperintelligent.com is an independent AI research and comparison platform built to help people navigate that complexity. It brings together software discovery, model selection, cost estimation, comparison frameworks, procurement guidance and transparent evaluation standards in one place.
Its defining principle is straightforward: a product claim is not the same as a verified result.
What does “research before rankings” mean?
Most AI discovery platforms compete to tell users which products are best. BestSuperintelligent.com begins with a more fundamental question: what evidence would justify calling one AI product better than another?
The distinction matters because AI software is unusually difficult to judge from marketing claims. A coding assistant might excel at generating new functions but struggle to modify a large, unfamiliar codebase. A model might perform well on a published benchmark yet prove unsuitable for a company's security requirements, budget or workflow. Even two tools with similar capabilities can produce very different outcomes depending on the task, the user and the implementation.
A meaningful comparison therefore needs more than a feature list and a star rating. It needs a defined evaluation process, traceable evidence, relevant testing conditions and a clear explanation of uncertainty.
What makes BestSuperintelligent.com different?
The platform distinguishes among six types of information:
- Vendor-reported: claims published by the product's developer or provider.
- Independently observed: findings documented through direct observation of a product.
- Independently measured: results obtained through an independent measurement or test.
- Third-party research: findings attributed to external research sources.
- Editorial interpretation: analysis and conclusions drawn from available evidence.
- Unverified: claims or information that have not been sufficiently substantiated.
Each claim is intended to carry a date and a source, so readers can see where information originated and how recently it was documented. This creates a distinction that conventional comparison pages often blur: the difference between what a company says its product can do and what an independent evaluator has actually demonstrated.
For developers choosing a coding agent, that distinction can decide whether a tool deserves a place in a production workflow. For an enterprise evaluating an AI supplier, it can show which claims need further testing before procurement. See vendor claims vs. verified findings for the full explanation.
It also sets a standard for the platform itself. BestSuperintelligent.com does not present its brand name as evidence that any existing AI system is superintelligent. The name is an identity, not a technical conclusion.
Why do AI tool rankings need a more rigorous method?
Rankings are useful when they explain what was compared, how products were tested and which criteria influenced the outcome. Without that, a ranking creates an illusion of precision. A numerical score can look authoritative even when it blends subjective impressions, vendor specifications and independently measured results without telling them apart.
BestSuperintelligent.com addresses this by making evaluation status visible and setting a threshold for publishing rankings. As of 18 October 2026, nine products are in the evaluation queue and none has completed an independent test. The queue is therefore presented alphabetically rather than as a ranking. The stated policy is not to publish a category ranking until at least two products have fully evidenced evaluations.
That policy has an important implication: the absence of a ranking is not a missing feature to be concealed. It is information users need to understand the maturity of the available evidence.
Inside the evaluation queue
The queue covers nine recognizable products across software development, research, productivity and creative work.
| AI product | Primary area of interest | What an independent evaluation could examine |
|---|---|---|
| Claude Code | AI-assisted software development | Repository-level changes, debugging, test execution, and task completion |
| Cursor | AI-powered code editing | Codebase understanding, editing workflows, and developer productivity |
| ElevenLabs | AI voice and audio | Speech quality, voice consistency, latency, and supported workflows |
| Gemini Code Assist | AI coding assistance | Code generation, debugging, and integration with supported development environments |
| GitHub Copilot | AI-assisted development | Coding workflows, suggestions, and supported agent capabilities |
| NotebookLM | Research and source-based synthesis | Source grounding, citation quality, and synthesis accuracy |
| Notion AI | AI-assisted knowledge work | Information retrieval, document workflows, and workspace integration |
| OpenAI Codex | AI coding agents | Task execution, code changes, testing, and software development workflows |
| Runway | AI video generation | Output consistency, creative control, generation performance, and workflow suitability |
The queue is designed to make the research process visible rather than presenting every listed product as a finished review. That matters in a fast-changing market, where products frequently introduce new models, capabilities, integrations and pricing. A comparison that was accurate several months ago may no longer describe the product users can buy today. By recording sources and dates, an evaluation can establish not only what was observed but when the finding was relevant.
The objective is not to eliminate uncertainty from AI purchasing. It is to make uncertainty visible enough for people to manage it.
How does the Model Finder turn model selection into a decision?
One of the platform's most useful tools is the Model Finder, an interactive quiz that narrows a complicated model-selection problem into a manageable set of candidates. Choosing an AI model is rarely as simple as picking the most powerful system available. A freelancer writing code, a researcher analyzing documents and an enterprise deploying an internal assistant may have completely different requirements.
The quiz screens 14 models and returns up to three to test. A three-question version sits on the home page and a five-question version has its own page. Its purpose is not to declare a universal winner. It is to help users identify a smaller, more relevant group of models for further evaluation.
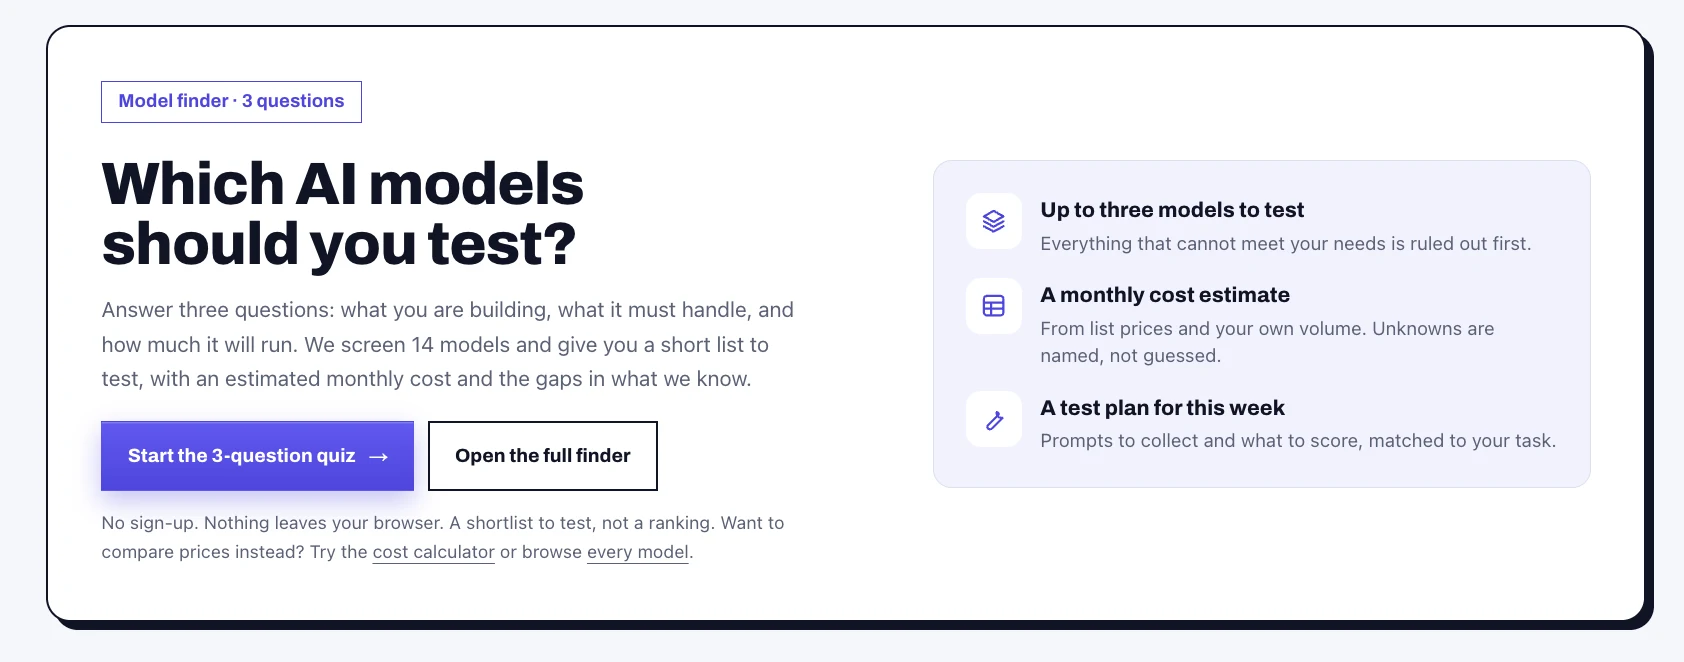
How the Model Finder works
- Define the requirementsAnswer a few questions that narrow the model-selection problem.
- Identify suitable candidatesThe tool screens its model set and returns up to three models for consideration.
- Plan a practical evaluationReview the estimated monthly cost and a suggested test plan before committing to a model.
This workflow addresses a common mistake in AI adoption: choosing a model on reputation or benchmark performance before defining the job it must perform. Consider a small software company that needs to generate code, debug functions, understand a repository and stay within a monthly budget. A model that excels at summarization might suit that workflow less well than one evaluated for coding tasks. The reverse could be true for an analyst working with long reports. The right starting point is the task, not the marketing leaderboard.
Why does a test plan matter more than a recommendation?
A shortlist can simplify discovery, but it cannot establish that a model will perform well in a specific environment. A useful evaluation plan defines:
- The tasks the model must complete.
- The expected quality and accuracy of its outputs.
- The acceptable error rate for consequential work.
- The time required to complete each task.
- The total cost under realistic usage.
- The privacy, security and integration requirements.
- The criteria for accepting or rejecting the result.
For a coding model, that could mean asking several candidates to solve the same representative issue in a test repository, run the available tests and explain their changes. For a research model, it could mean checking whether its answers are supported by the supplied documents and whether its citations substantiate its conclusions. The Model Finder connects product discovery to that next step: testing candidates against the work you actually need done. The model data and prices behind it are as supplied and are checked against vendor pages where noted.
How should businesses calculate the real cost of an AI model?
AI pricing can be deceptively difficult to compare. A subscription fee is only one component. Depending on the product and deployment model, users may also need to consider usage limits, API consumption, additional services, infrastructure, team seats, and the cost of reviewing or correcting generated output. The site's cost calculator is intended to help users assess the financial side of adoption alongside model selection.
A useful cost model starts by defining the workload rather than comparing prices in isolation. For an organization evaluating two API-based models, a first estimate is:
Estimated monthly API cost = input tokens × input-token price + output tokens × output-token price, with both token counts expressed in the pricing units the provider uses. If pricing is quoted per million tokens, divide each token count by one million before multiplying by the rate.
| Cost component | What it measures | Why it matters |
|---|---|---|
| Input consumption | Tokens or other billable inputs sent to the model | Workloads with extensive context can increase input costs |
| Output consumption | Generated tokens or other billable outputs | Long responses and generated code can increase spending |
| Subscription or seat fees | Recurring access charges | Team plans may have costs beyond usage-based pricing |
| Additional services | Tools, storage, integrations, or other billable components | The model itself may not be the entire service cost |
| Human review | Time spent checking, correcting, or approving output | Cheap generation may not translate into cheap completed work |
| Operational overhead | Implementation, monitoring, and maintenance | Production deployments require more than model access |
The last two rows are particularly important. Suppose one model produces an acceptable result in a single attempt while another needs several retries and substantial human correction. The second might have the lower advertised price but the higher cost per completed task. Conversely, a more expensive model could prove attractive if it reduces review time or handles difficult work more reliably. Pricing data alone cannot settle this; it takes workload-specific measurement.
That is why a cost estimate should be treated as a planning tool, not a guarantee of future spending. The better question for buyers is not which model costs less, but which delivers sufficient quality for the total cost of the work it performs.
What would a credible AI coding-tool comparison look like?
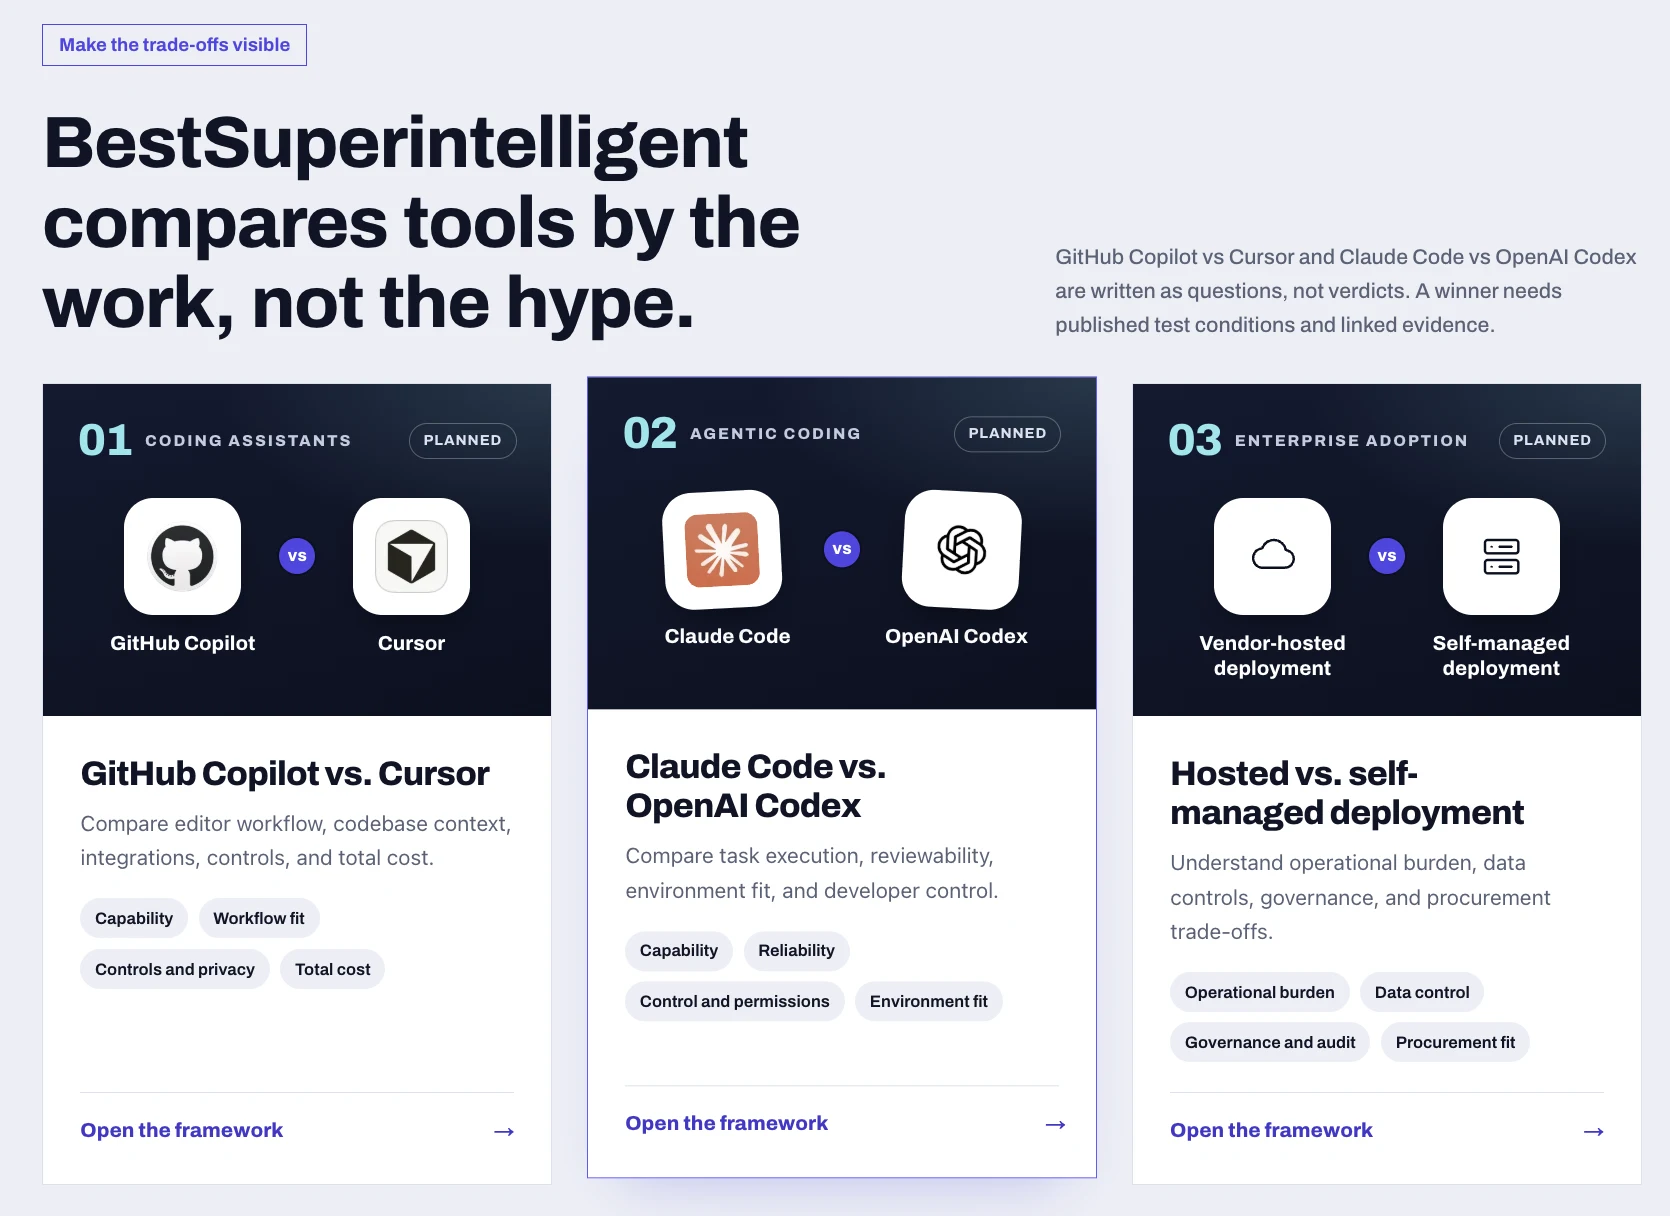
Direct comparisons are among the most useful forms of AI research, and among the easiest to oversimplify. A headline such as “Copilot vs. Cursor” or “Claude Code vs. Codex” implies a contest. The meaningful answer depends on what is being compared, which versions are tested, what tasks are assigned and how success is measured. BestSuperintelligent.com frames these as questions accompanied by the evidence needed to answer them, in its comparison frameworks.
A rigorous comparison begins with a defined set of tasks drawn from representative development work. Each product receives equivalent instructions, access to equivalent resources and clearly documented conditions. The evaluation might then examine:
- Task completion: did the tool accomplish the requested work?
- Correctness: did the implementation produce the intended behavior?
- Test results: did the relevant automated tests pass?
- Code quality: were the changes understandable, maintainable and appropriately scoped?
- Repository awareness: did the tool correctly interpret project structure and dependencies?
- Human intervention: how much guidance or correction was required?
- Time and cost: what resources were consumed to achieve the result?
- Reproducibility: could another evaluator repeat the procedure and inspect the findings?
A credible report documents failures as well as successes, and distinguishes a product's native capabilities from performance that depends on extra configuration, external tools or particular model settings. The outcome might favor one product for complex repository changes and another for a different workflow. It might also find that the evidence does not establish a meaningful difference. All three conclusions are useful if they follow from the same transparent method.
Why do versions and dates matter?
AI systems evolve quickly enough that the identity of the tested product must be part of the evidence. A comparison should record the product or model version, the testing date, the configuration and any important limitations. If a product changes materially, earlier results should not automatically be treated as evidence of its current performance. The same applies to pricing, security documentation and feature availability. By placing source dates and evaluation status at the center of its research model, the site aims to keep comparisons accountable to the conditions under which their conclusions were reached.
Which AI categories does the platform cover?
The AI market is no longer confined to chatbots and coding assistants. People increasingly meet AI through research applications, writing tools, speech systems, video generators, data products and enterprise software. A discovery platform that treats these categories as interchangeable risks recommending tools that solve the wrong problem. BestSuperintelligent.com organizes its coverage around distinct entry points so users can begin with the category that matches their objective.
| Platform section | Core purpose | Intended audience |
|---|---|---|
| AI Coding Tools | Explore software development assistants and coding agents | Developers, engineering teams, and technical founders |
| AI Agents | Investigate systems designed to execute multistep tasks | Developers, operators, and businesses exploring automation |
| AI Research Tools | Discover tools for research, document analysis, and knowledge work | Researchers, students, analysts, and knowledge workers |
| AI Writing Tools | Explore applications for drafting, editing, and content production | Writers, marketers, and professionals |
| AI Image and Video | Investigate generative visual and video applications | Designers, creators, and media teams |
| AI Speech | Explore voice generation and audio-related applications | Creators, product teams, and accessibility-focused users |
| AI Data Tools | Examine tools for working with data and analytical workflows | Analysts, data teams, and technical users |
| Enterprise and Government | Consider organizational requirements for adopting AI | Procurement teams, security professionals, and decision-makers |
| Models and Data | Explore model-selection considerations and relevant information | Technical evaluators and AI practitioners |
The distinction between discovery and evaluation runs through all of it. A category page can help users understand which products exist and what they are designed to do. A completed evaluation must go further and examine evidence about actual performance. Keeping those functions separate lets the platform be useful while its independent research program develops. For a developer, the journey might begin with coding tools, continue through a comparison framework and lead to the Model Finder. For a government buyer, it might begin with enterprise requirements and proceed to security evidence and procurement guidance. The principle is the same: the tool should fit the task, and the evidence should fit the decision.
What evidence should organizations request before adopting AI?
For individual users, a poor AI recommendation can mean wasted time or an unnecessary subscription. For an organization, an unsuitable tool can introduce operational, contractual, privacy and security risks. A tool may perform strongly in a technical evaluation and still be unsuitable because of its data-handling practices, access controls, contractual terms or deployment requirements.
The site addresses this through procurement guidance, security-evidence standards and a policy tracker. A responsible assessment examines several distinct areas.
Data handling and privacy
- What information does the system collect and process?
- Is submitted data used to train models, and under what conditions?
- What retention and deletion controls are available?
- Which subprocessors or external services may receive the data?
Security and access control
- What authentication and authorization mechanisms are supported?
- Are administrative controls available for the intended deployment?
- What security documentation and independent assessments can the vendor provide?
- How are vulnerabilities, incidents and security updates handled?
Governance and contractual obligations
- What contractual commitments apply to data use and confidentiality?
- Can the organization establish appropriate audit and oversight procedures?
- Which legal, regulatory and internal policy requirements apply?
- What happens to organizational data if the service is discontinued?
Operational suitability
- Does the product integrate with the organization's existing environment?
- Can the organization monitor usage, performance and expenditure?
- Are service availability and support commitments adequate?
- Can the system be evaluated safely before wider deployment?
These questions are not interchangeable, and no single certification or vendor statement resolves all of them. The evidence required depends on the product, the data involved, the intended use and the organization's risk profile. A developer experimenting with a public coding assistant has different requirements from a financial institution processing confidential information or a government department handling sensitive records.
The important distinction is between a vendor having documentation and that documentation establishing suitability for a specific deployment.
Why is transparency also a product feature?
Comparison platforms routinely ask readers to trust their recommendations. BestSuperintelligent.com takes the position that trust should also be supported by information about how recommendations are produced. Its trust framework includes a methodology page, an editorial policy, an affiliate disclosure and a dated corrections log. Together they let readers ask:
- How are products selected for evaluation?
- What evidence is required before a claim is treated as established?
- How are editorial conclusions distinguished from measured results?
- What commercial relationships could influence coverage?
- How are errors corrected after publication?
These questions matter most when a publication earns revenue through affiliate relationships or sponsorships. Commercial funding does not by itself establish bias, and a disclosure does not by itself establish independence. What matters is whether readers can understand the relationship, inspect the methodology and evaluate the evidence behind the conclusions.
The site states that affiliate and sponsorship relationships may generate revenue and that its scores are computed by code that takes no commercial input. That is a specific, testable design principle: commercial relationships should not directly determine numerical results. It also deserves ongoing scrutiny. Readers should be able to see how the scoring code works, what evidence enters the evaluation and which editorial judgments remain outside the calculation. A transparent methodology does not eliminate disagreement; it makes disagreement more productive by giving readers a basis for examining the reasoning.
Why does the corrections log matter?
An editorial policy describes the rules a publication intends to follow. A corrections log records how it responds when information proves inaccurate or incomplete. In AI research that distinction is especially relevant: a model's capabilities may change, a vendor may update its documentation, or a later test may reveal a problem that was not apparent earlier. A correction record helps readers tell an article that was wrong from one that has become outdated and from one whose conclusions changed as new evidence emerged. The strongest trust systems make these changes visible rather than quietly replacing the original claims.
How is the research designed for people and answer engines?
As users increasingly turn to AI assistants and answer engines for product research, publications need to make their findings understandable to both people and the systems that extract answers from documents. The site's structure supports that with clearly separated product information, explicit evaluation labels, question-led comparison frameworks, tables, practical guides and a glossary. These structures can improve readability and make it easier to identify the precise claim a page supports.
However, clear structure is not a guarantee of Google rankings or inclusion in AI-generated answers. Visibility depends on content quality, technical accessibility, competition, reputation and the usefulness of what is published. The potential advantage here is not guaranteed discovery. It is an evidence-oriented content model that lends itself to answers that can be examined rather than merely repeated.
- A direct answer: state what the product does or what the comparison establishes.
- Clear attribution: identify whether the information comes from a vendor, an independent test or editorial interpretation.
- Traceable evidence: link to original documentation, test results or other relevant sources.
- Defined scope: explain which version, configuration, date or use case the finding covers.
- Explicit limitations: state what the evidence does not establish.
- Useful relationships: connect the answer to related comparisons, methodology and supporting research.
A page comparing two coding assistants should not simply state that one is faster. It should explain the tasks measured, the conditions, the metric used and the limits of the result. That gives human readers the context to interpret the finding and gives retrieval systems a more clearly defined claim to extract.
The wider editorial structure extends beyond product pages. Guides address practical questions about selecting and deploying AI tools. The glossary fixes definitions. Procurement resources help organizations identify relevant evidence. The policy tracker follows developments in AI rules and governance. The long-term value of this structure will depend on whether the pages contain original, current, well-supported information, not merely on whether the sections exist.
Can a small AI research platform compete with the industry's biggest names?
BestSuperintelligent.com faces a difficult challenge. The AI market moves quickly, and the companies producing the products also control much of the technical information needed to understand them. Independent evaluation takes time, technical expertise, reproducible testing and continuous maintenance.
The evaluation queue makes that challenge visible. Nine products are identified for evaluation, but no independent test has been completed. That is an important limitation, and it should stay explicit. A transparent queue shows what the publication intends to investigate; it is not a substitute for completed research. Likewise, a well-designed Model Finder helps narrow candidates, but its output does not independently prove product quality. The platform's long-term credibility depends on turning its stated method into a sustained body of evidence. Five developments would make that progress particularly valuable.
What would build credibility
- Reproducible, task-based testingPublished evaluations should include test objectives, product versions, configurations, scoring criteria and enough detail for readers to see how conclusions were reached, ideally with representative test cases and results.
- Meaningful historical recordsAs products evolve, earlier results should stay interpretable. Dated evaluations and version histories show whether an observed difference persists across updates.
- Stronger evidence for high-stakes decisionsEnterprise and government buyers need documented information on security, privacy, governance and operational suitability, separating missing documentation, vendor assertions and independent verification.
- A clear separation between discovery and proofEditorial recommendations, preliminary assessments and completed independent evaluations should stay distinct, so not every recommendation is presented as a proven result.
- Commercial independence that can be examinedDisclosures and code-based scoring are useful starting points. Their value grows when readers can understand the scoring method and verify that commercial considerations do not determine outcomes.
None of this is automatic. Each step requires sustained editorial and technical work. But together they offer a credible direction for an independent AI research publication: build trust through a growing record of documented findings rather than claims of authority.
BestSuperintelligent.com at a glance
| Question | Answer |
|---|---|
| What is it? | An independent AI research and comparison platform focused on software discovery, model selection, evaluation methods and purchasing decisions. |
| Who is it for? | Developers, freelancers, team leads, researchers, businesses, and enterprise or government buyers. |
| What problem does it address? | The difficulty of evaluating AI products amid competing claims, changing capabilities, uncertain costs and incomplete evidence. |
| How does it distinguish evidence? | It labels information by source and status, separating vendor claims from independent observations, measurements, third-party research and editorial interpretation. |
| What is the Model Finder? | A quiz that screens 14 models and returns up to three candidates to test, with a monthly cost estimate and a test plan. |
| What other tools does it offer? | A cost calculator, model data, category-based discovery and structured comparison frameworks. |
| How does it support organizational buyers? | Through procurement guidance, security-evidence standards and policy tracking. |
| Does it have completed independent evaluations? | No. None of the nine products in the initial evaluation queue has completed an independent test. |
| When does it publish a category ranking? | Only after at least two fully evidenced evaluations exist in that category. |
| How may it generate revenue? | Through disclosed affiliate or sponsorship relationships, while its scoring code excludes commercial input. |
| Does the name mean listed products are superintelligent? | No. The name is a brand, not a claim about the intelligence of any product. |
What should an AI recommendation be worth?
The AI industry has spent years making systems more capable, accessible and easy to use. The next challenge is helping people decide which capabilities are real, which are relevant, and which justify the costs and risks of adoption.
A developer needs to know whether an assistant can solve a particular class of software problems. A researcher needs to know whether a model can synthesize documents without inventing supporting evidence. A business needs to understand the relationship between model quality, operating cost and human oversight. An enterprise needs to know whether a system meets its security and governance requirements. These are related questions, not the same question, and they demand different forms of evidence.
BestSuperintelligent.com proposes a framework that brings them into one research environment. Category pages support discovery. The Model Finder narrows the options. The cost calculator addresses money. Comparison frameworks identify the evidence needed to answer product-specific questions. Procurement and security resources extend the analysis to organizational adoption.
If it can turn its evidence-first principles into reproducible testing, transparent comparisons, current documentation and useful guidance, it could become a valuable resource in an increasingly complicated AI market. Its most important contribution would not be another list of supposedly superior AI products. It would be helping readers understand what better actually means, how to measure it, and when the available evidence is strong enough to justify a decision.
The future of AI discovery may depend less on finding the loudest recommendation and more on finding the evidence that makes a recommendation worth trusting.
Start with the evaluation queue, the Model Finder or the methodology.
Evidence in this article Editorial interpretation Our reading of what the evidence means. Judgment, clearly separated from the evidence itself.
Frequently asked questions
What is BestSuperintelligent.com?
An independent AI research and comparison site focused on software discovery, model selection, evaluation methods and purchasing decisions. It labels claims by source and status instead of presenting vendor statements as proven results.
Does it have completed independent evaluations?
No. Nine products are in the evaluation queue and none has completed an independent test. The queue is shown alphabetically, not as a ranking.
When will it publish a category ranking?
Its stated policy is to publish no ranking in a category until at least two products there have fully evidenced evaluations.
Does the name mean the listed products are superintelligent?
No. The name is a brand, not a technical claim about any product's intelligence.
How can the site earn revenue?
Through disclosed affiliate or sponsorship relationships. Its scoring code takes no commercial input, and the affiliate disclosure page explains the arrangement.
Sources
This article is editorial analysis. It cites no external sources and contains no product performance claims, benchmark figures, or policy facts.